Over the past few years, the way we use large language models has settled into a fairly fixed pattern:
Whether it’s ChatGPT, a coding agent, or any agent framework, the core underneath is still a text generation model.
The model generates tokens first, and then we figure out how to turn those tokens into a structure a program can work with.
But a lot of software doesn’t actually need the model to “talk.”
For example:
Which team should this request go to?
Is this alert severe?
Is this tool call risky?
Does this email need a reply?
Is this message spam?
These questions don’t need a paragraph of natural language back. They need a judgment.
That’s exactly the problem TypeSafe AI’s newly released Jev is trying to solve.
On September 15, 2026, TypeSafe AI released what it calls the first System One Model: Jev. Its primary goal isn’t generating strings — it takes in program state plus a predefined question and returns a structured judgment directly. TypeSafe sums it up as:
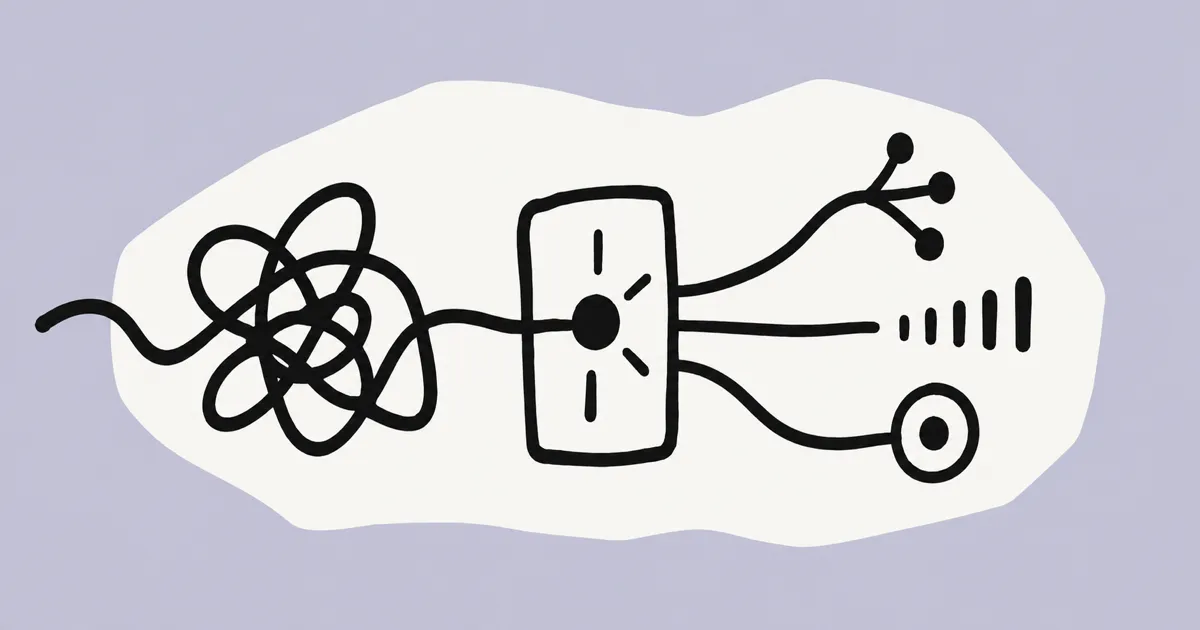
unstructured state in → typed probabilistic decisions out
In other words:
Instead of:
That looks like it’s just skipping one generated block of text, but the programming model underneath is actually quite different.
Understanding Jev: an AI-powered fuzzy if statement
I think the simplest way to understand Jev is to picture it as:
A regular program handles this without trouble:
Because cpuUsage > 90 is deterministic.
But a huge share of real-world judgments aren’t nearly this clean.
For example:
Or:
You could keep stacking rules, of course:
The problem is that language and software state are inherently fuzzy, and no rule list ever fully catches up.
This is exactly the kind of thing an LLM is good at judging, but a traditional LLM feels like overkill for it — having a model generate dozens or hundreds of tokens just to land on a single true is a lot of overhead for the answer you actually wanted.
Jev’s approach is to train a model specifically to make this kind of call.
TypeSafe’s official docs currently define three basic question types: Choice (pick from a finite set of options), Score (rate against a rubric), and Noul (the probability that a statement holds).
The type definitions alone are pretty abstract, so here’s the same batch of support tickets fed into all three types — click a ticket to switch the message and watch the return structure change.
Which team should this message be routed to?
Help! My payout has failed for 3 days in a row and customers keep complaining.
choice: technical · confidence: 0.74Illustrative data showing the Choice return shape (choice + probabilities + confidence); not a real API response.
View raw JSON
Input
{}Output
{}How intense is the customer's emotion in this message?
Help! My payout has failed for 3 days in a row and customers keep complaining.
score: 1.4Illustrative data showing the Score return shape (score + legend + probabilities + confidence); not a real API response.
View raw JSON
Input
{}Output
{}Does this message need to be escalated to a human right away?
Help! My payout has failed for 3 days in a row and customers keep complaining.
noul: 0.94Leans "yes" — recommend escalatingIllustrative data showing the Noul return shape (only a single noul field, no separate confidence); not a real API response.
View raw JSON
Input
{}Output
{}And all three questions can be computed in a single request — the three demos above are actually using the same ticket: the official docs use it to ask department (Choice), frustration (Score), and is_urgent (Noul) all at once, in one call.
Once the software has these values, it doesn’t need to understand any natural language at all — it can just run code.
How Jev differs from Structured Output (JSON mode)
The first reaction is probably:
Doesn’t JSON mode / Structured Output on an LLM already do this?
On the surface, it really does look similar.
For example, having an LLM return:
But underneath, it’s still:
The model is still generating a string — it’s just a string constrained by a schema.
Jev, by contrast, doesn’t treat “generate an arbitrary string” as the objective at the model-interface level at all. Its output space is defined ahead of time.
TypeSafe’s official comparison frames the difference this way: an LLM generates text for humans, while a System One Model generates typed decisions for software. Jev can also compute multiple judgments in parallel, rather than generating tokens one at a time, autoregressively.
That makes it particularly well-suited to a different kind of AI workload: high-frequency, simple, fuzzy judgments that a program needs to consume right away.
“No hallucinations” doesn’t mean “never wrong”
TypeSafe’s own docs also emphasize that Jev doesn’t produce hallucinations in the traditional sense, because its output can only land inside a predefined data structure — schema matching guarantees there’s no type error.
That doesn’t mean Jev is always right, though. It can still classify a bug as a feature, or misjudge risk.
The more accurate way to put it: not producing an invalid answer isn’t the same as not producing a wrong answer.
For instance, if you define a Choice with only ALLOW, ASK, and BLOCK as options, Jev won’t suddenly answer “I think you should probably ask the user…” — it will always land on one of those three allowed options.
Handling “it might still judge wrong” is a job for probability + confidence + software policy, not the model itself:
AI no longer owns the whole workflow — it’s only responsible for this one judgment. Questions like “when do we trust the AI,” “when do we escalate to a human,” and “what’s ultimately allowed to happen” are all decided by ordinary code.
Jev and agents are complementary, not competing
A lot of current agent architectures look like this:
Hiding inside that loop are a lot of small judgments:
Is this tool call reasonable?
Is this search result relevant?
Is this observation worth putting into context?
Which sub-agent should handle this task?
Is the current step actually done?
How risky is this action?
Routing every one of those questions through a large reasoning model gets expensive fast, and the latency keeps stacking up.
So it can instead become:
The large model handles what actually needs generation, planning, reasoning, coding, or explanation.
Jev handles the “Should I? Which one? How much? Is this true?” category of question.
That’s arguably a more engineered architecture than “let one agent handle everything.”
Why models like Jev are worth paying attention to right now
TypeSafe has published Jev’s pricing at $0.042 per million input tokens, with no separate charge for output; server-side end-to-end latency runs roughly 70–500ms. It’s worth noting these numbers come from TypeSafe’s own current testing and serving environment, so they’re better read as vendor-reported figures than as a universal benchmark result.
What I find interesting isn’t “how much cheaper it is” — it’s that the unit of what a model is used for has shifted.
We used to ask:
Can I drop an LLM in here?
Going forward, it might become:
Is there an
ifhere that a rule can’t express accurately?
If the answer is yes, there’s probably room for a small AI decision model right there.
Traditional code handles determinism, a large LLM handles complex reasoning and generation, and a model like Jev tries to fill the wide gap in between that’s historically been hard to handle:
It’s not necessarily trying to build a smarter chatbot — it looks more like an attempt at a new software primitive:
If this pattern actually sticks, a lot of if statements in future software might genuinely start carrying a bit of intelligence.